ebrahim.gof
Goodness-of-Fit and Calibration Tests for Logistic Regression
Provides a unified battery of goodness-of-fit and calibration
tests for binary logistic regression, runnable in a single call via
'run.all.gof()'. Around twenty-five tests spanning five decades of
literature are aggregated and grouped by the departure each is built to
detect: global and standardized statistics, partition tests such as
Hosmer-Lemeshow, directed and covariate-space tests, smoothing and
resampling tests, and calibration tests. Each is obtained from its own
package where installed and attributed to its authors. The package also
implements the author's own procedures for sparse data, where the
Hosmer-Lemeshow test loses power: the omnibus Ebrahim-Farrington test
'ef.gof()', the directed 'edge.gof()' and its covariate-space variant
'cdef.gof()', the Cauchy-combination ensemble 'edges.gof()', 'DeepGOF-1'
(a pretrained convolutional statistic whose level comes from the analyst's
own parametric bootstrap rather than from the network), and 'legoft()'
(a frozen-weight combination whose weights are fixed offline and ship
frozen, so two analysts obtain the same p-value). For penalized (ridge)
logistic regression, where shrinkage biases the fitted probabilities and
invalidates the usual chi-squared references, the corrected statistics are
referred either to a prepivoting bootstrap by 'shrink.gof()' or to a
closed-form reference by 'calm.gof()', which needs a single fit and is
validated for designs in which the number of predictors is a sizeable
fraction of the sample size. For a model fitted elsewhere, 'run.all.external()'
tests frozen predictions on validation data, and 'edge.stream()' updates the
'EDGE' test as validation records arrive. 'localize.gof()' and
'localize.external()' name which part of the model is wrong (the intercept,
the slope, the link or the covariates) with familywise error control. For
comparison, the projection test of Liu et al. is implemented as
'projection.gof()' and a fast implementation of the adaptive-partition test
'BAGofT' as 'bagoft.fast()'. For more details see Hosmer (1980)
ebrahim.gof — Goodness-of-Fit and Calibration Tests for Logistic Regression
Overview
ebrahim.gof is a unified toolbox of goodness-of-fit and calibration tests for binary logistic
regression, callable in a single line via run.all.gof(). It is particularly suited to sparse data,
where the traditional Hosmer-Lemeshow test loses power.
The package introduces the author's own sparse-data tests — the omnibus Ebrahim-Farrington (EF) test
(ef.gof()), the Directed EF / EDGE test (def.gof() / edge.gof()) that targets smooth
calibration-shape departures, and a Cauchy-combination ensemble (def.ensemble.gof()) — and aggregates
a wide range of classical and modern tests for comparison (Hosmer-Lemeshow, McCullagh, Osius-Rojek,
le Cessie-van Houwelingen, Stute-Zhu, the binary-adaptive BAGofT test, and the GiViTI calibration test),
each obtained from its own package where installed and attributed to its authors.
See the vignette "A goodness-of-fit and calibration toolbox for logistic regression"
(vignette("ebrahim-gof-toolbox", package = "ebrahim.gof")) for a full walkthrough on the bundled
gof_demo dataset.
Key Features
- Ebrahim-Farrington Test (
ef.gof()): omnibus test for binary data with automatic grouping (chi-square or normal reference) - Directed EF Test (
def.gof()): targets calibration-shape departures (poly2/poly3/stukel/sym bases or their ensemble) - Ensemble (
def.ensemble.gof()): combines the DEF bases via the Cauchy combination test - One-shot battery (
run.all.gof()): runs ~20+ GOF & calibration tests (plus opt-in slow ones) and returns a tidy data frame - Original Farrington Test: Full implementation for grouped data
- Robust Performance: Particularly effective with sparse data and binary outcomes
- Well Documented: Comprehensive documentation with examples
Installation
New here? Start with these two lines.
install.packages("ebrahim.gof")   # core battery — nothing else needed
library(ebrahim.gof)              # on load, it tells you if any optional
                                  # packages are missing and how to add them
The core battery runs out of the box (only
parallel+statsare required). A few slow tests (GAM,BAGofT,GiViTI, Lai–Liu–HL) need optional packages — when they are missing,library(ebrahim.gof)prints a one-time hint, and you can install them all at once withgof_install_suggests(). Missing packages are never installed silently, and any test whose package is absent is simply skipped with a note (nothing errors).
From GitHub (Development Version)
Copy and paste this in R or R-studio.
# Install devtools if you haven't already
if (!requireNamespace("devtools", quietly = TRUE)) {
  install.packages("devtools")
}

# Install ebrahim.gof from GitHub
devtools::install_github("ebrahimkhaled/ebrahim.gof")
From CRAN (Stable Version)
The released version is on CRAN:
install.packages("ebrahim.gof")
The development version, with any tests newer than the CRAN release, is on GitHub. What each release added is listed in NEWS.md.
Quick Start
library(ebrahim.gof)

# Example with binary data
set.seed(123)
n <- 500
x <- rnorm(n)
linpred <- 0.5 + 1.2 * x
prob <- 1 / (1 + exp(-linpred))
y <- rbinom(n, 1, prob)

# Fit logistic regression
model <- glm(y ~ x, family = binomial())
predicted_probs <- fitted(model)

# Perform Ebrahim-Farrington test
result <- ef.gof(y, predicted_probs, G = 10)
print(result)
Main Functions
ef.gof()
The main function that performs the goodness-of-fit test:
ef.gof(y, predicted_probs = NULL, model = NULL, m = NULL, G = 10,
       method = NULL, reference = c("chisq", "normal"), X = NULL, groups = NULL)
Parameters:
y: a fitted binary-logisticglm(thenpredicted_probsandXare taken from it), or a binary response vector (0/1) / success counts for grouped datapredicted_probs: Vector of predicted probabilities from logistic modelG: Number of groups (default: 10);"auto"for groups of about 25 records;"paul"for the rule of Paul, Pennell and Lemeshow (2013)reference:"chisq"(default) refers EF to a chi-square with G-2 df;"normal"is the plug-in normal reference for many groups (needs the fittedglmorX)groups:NULL(equal-size groups by fitted risk, ties at random),"pattern"(one group per covariate pattern), or a vector of group labelsmethod: deprecated;method = "normal"reproduces the standardization of versions up to 2.9.0model: Optional glm object (required for the original Farrington test only)m: Optional vector of trial counts (for grouped data; original Farrington only)
The result carries C = HL - EF and, in attr(result, "groups"), the per-group read-out c = b r.
Note (behaviour change in 2.10.0): the groups are equal in size to within one record, tied fitted risks are put in random order (call
set.seed()first), andTest_Statisticis EF itself. See NEWS for how to reproduce an earlier p-value.
Returns: A data frame with test name, test statistic, and p-value.
run.all.external() — external validation in one call
For predictions made without the data at hand, such as a published model checked on new patients or any machine-learning model scored on a validation set, pass the outcomes and the predicted probabilities. Nothing is refitted, so every test uses its external reference.
run.all.external(y, p, G = 10, X = NULL, include_slow = FALSE)
It returns the directed test in external mode (ten groups and G = "auto"), Cox's recalibration test,
calibration in the large, Spiegelhalter's z, Osius-Rojek's standardized Pearson statistic with its
external moments, the GiViTI test (external), the Hosmer-Lemeshow statistic on
chi-squared(G), Stukel's test on the frozen linear predictor, le Cessie's test when X is given and
include_slow = TRUE, and the O/E ratio, calibration slope and c-statistic.
edge.stream() — monitoring a deployed model
s <- edge.stream(p_ref = p_dev, G = 10)   # cut points from the development predictions
s <- update(s, y_new, p_new)              # each new batch, constant time per patient
summary(s)                                # the external-mode test on everything seen so far
The result equals the one-shot external test on the same groups. One test at any time is valid; if you test after every batch, spend the level over the looks (for example 0.05 / number of looks).
def.gof() — Directed Ebrahim-Farrington test
Concentrates power on calibration-curve shape directions by projecting the grouped residuals onto a small smooth basis.
def.gof(object, predicted_probs = NULL, X = NULL, G = 10,
        basis = c("poly3", "poly2", "stukel", "sym", "ensemble"),
        method = c("satterthwaite", "imhof"),
        weights = c("unit", "score"), external = FALSE)
object: a fitted binary-logisticglm, or a 0/1 response vectory(then givepredicted_probs, andXto get the exact calibration).external:TRUEchecks frozen predictions, as in external validation of a published model on new data: Omega is the identity, a constant column joins the basis, and the statistic is referred to chi-squared on d + 1 degrees of freedom (unit weights only).G: the number of equal-frequency groups (default 10), or"auto"formax(10, ceiling(n / 25)), the partition rule of the EDGE paper.basis:"poly3"(default),"poly2","stukel","sym"(one column, eta|eta|, Stukel's symmetric tail direction), or"ensemble"(runs poly2, poly3 and stukel and combines them viadef.ensemble.gof()).method:"satterthwaite"(default, no extra dependency) or"imhof"(exact, needsCompQuadForm).weights:"unit"(default, the published statistic) or"score", which weights each basis column by the square root of its group's variance. For a logit fit this makes the statistic the Rao score test for adding the grouped shape to the model (for other links it is a score-type test). It is referred to chi-squared on the rank of its information matrix, which is the number of columns unless one is redundant.
fit <- glm(y ~ x1 + x2, family = binomial())
def.gof(fit)                                   # default poly3 basis
def.gof(fit, basis = "sym", weights = "score") # symmetric tail direction, score form
def.gof(fit, basis = "ensemble")               # combined Cauchy decision
def.ensemble.gof() — combine the DEF bases
Combines the three DEF basis tests (optionally the omnibus EF, or extra p-values) into one decision via the Cauchy combination test (CCT).
def.ensemble.gof(fit)                # CCT of poly2 + poly3 + stukel
def.ensemble.gof(fit, add_ef = TRUE) # add the omnibus EF
run.all.gof() — the whole battery in one call
Runs a large battery of goodness-of-fit tests and returns one tidy data frame (one row per test). A failing test never aborts the run.
fit <- glm(low ~ age + lwt + factor(race), data = MASS::birthwt, family = binomial())
run.all.gof(fit)                       # the default (fast) battery + ensemble rows
run.all.gof(fit, include_slow = TRUE)  # also the opt-in slow tests
run.all.gof(fit, tests = c("EF", "DEF.poly3", "HL"))   # a chosen subset
run.all.gof(y, fitted(fit))            # prediction-only tests (no model)
Default fast battery (25 rows on fully sparse data with more than 250 records):
Pearson, Deviance, Information-Matrix, Osius-Rojek, McCullagh, Copas-RSS,
Hosmer-Lemeshow (deciles, large-sample and equal-width), Pigeon-Heyse, the F-test,
EF, EF-normal, EDGE at its two partitions, the DEF bases poly2, stukel and sym,
Stukel's joint score test, Tsiatis, Xie, Pulkstenis-Robinson, Cubic-LR and the two
Cauchy-combination ensemble rows. The sparse Pearson and deviance statistics and the
F-test are printed for comparison only and are not counted as rejections. With include_slow = TRUE it also runs
le Cessie-van Houwelingen, the GAM-based tests (HL-GAM, PR-GAM, Xie-GAM; need
mgcv), Stute-Zhu, eHL, BAGofT (computed by bagoft.fast()), the projection test of
Liu et al. (2024) (projection.gof()), and the Lai & Liu standardized-power HL test.
Every test reproduces the implementation used in the original thesis simulation.
Optional packages for the slow tests
The slow tests rely on a few optional packages (givitiR + callr for the
GiViTI calibration test and belt, mgcv for the GAM tests, randomForest and
dcov for BAGofT,
ResourceSelection). They are not required to install ebrahim.gof; a test
whose package is missing is simply skipped with a note. CRAN policy forbids a
package from installing anything on its own, so ebrahim.gof never does that
silently. Instead, in an interactive session run.all.gof() offers to
install any missing package it needs (the default install = "ask"), and you
can install them all up front at any time:
gof_install_suggests()                 # asks, then installs only the missing ones
gof_install_suggests(update = TRUE)    # also update any that are out of date
gof_install_suggests(ask = FALSE)      # install without a prompt (setup scripts)

run.all.gof(fit, include_slow = TRUE)               # asks to install if needed
run.all.gof(fit, include_slow = TRUE, install = "no")  # never ask, just skip
In a non-interactive session (scripts, R CMD check) nothing is ever installed,
regardless of the install setting.
Power and size: the partition-based family
Most goodness-of-fit tests for logistic regression are partition-based: they
split the data into groups — by the fitted probability, by covariate-space
clusters, or by categorical patterns — and compare observed with expected event
counts in each group. This is the family that ef.gof(), def.gof(), and
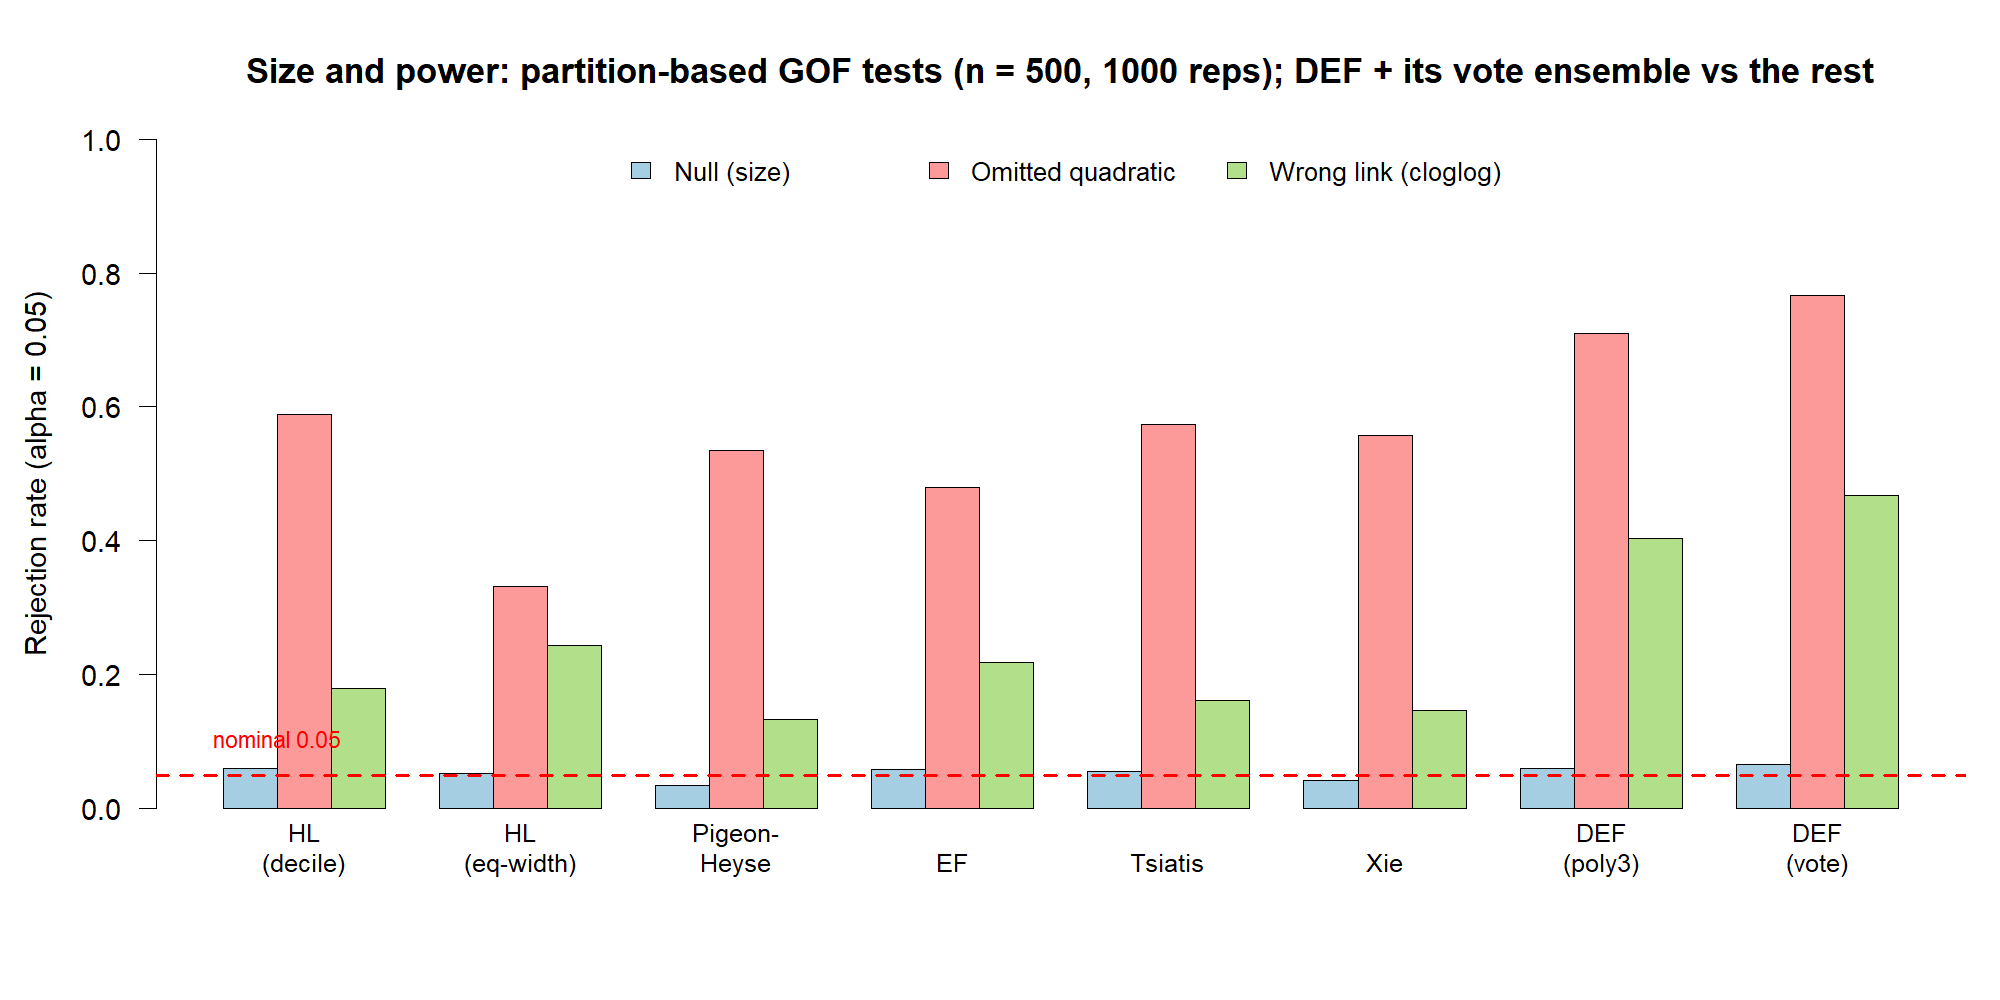
def.ensemble.gof() belong to. In a Monte Carlo study (n = 500, 1000 replications,
α = 0.05) the partition tests compare as follows:
| Test | Grouping | Size (null) | Power: quadratic | Power: wrong link |
|---|---|---|---|---|
| Hosmer–Lemeshow (decile) | fitted prob | 0.060 | 0.588 | 0.179 |
| Hosmer–Lemeshow (equal-width) | fitted prob | 0.053 | 0.332 | 0.244 |
| Pigeon–Heyse | fitted prob | 0.035 | 0.535 | 0.133 |
| EF (omnibus) | fitted prob | 0.058 | 0.480 | 0.218 |
| Tsiatis | covariate clusters | 0.056 | 0.574 | 0.162 |
| Xie | covariate clusters | 0.042 | 0.557 | 0.147 |
| DEF (poly3) | fitted prob + shape basis | 0.060 | 0.709 | 0.404 |
| DEF (ensemble, vote) | fitted prob + 3 bases | 0.066 | 0.767 | 0.468 |
Across the family, DEF and its vote ensemble are the most powerful while keeping the size near the nominal 0.05 — they are not liberal — and they roughly double the power of Hosmer–Lemeshow, Tsiatis, and Xie on the wrong-link misfit.
Pros and cons of partition-based tests
Pros
- Intuitive — compare observed vs expected event counts within groups.
- Work for sparse data and continuous covariates, where the classical Pearson and deviance chi-square tests break down (those need replicated covariate patterns).
- Widely used and understood (Hosmer–Lemeshow is the de-facto standard).
- Flexible — group by the fitted probability (HL, EF, Pigeon–Heyse, DEF) or by the covariate space (Tsiatis, Xie) to target different kinds of misfit.
Cons
- The result depends on the grouping choice — the number of groups
Gand the grouping rule. Hosmer–Lemeshow in particular is known to give different answers for differentGand across software. - Limited power for some departures — omnibus partition tests (HL) spread their few degrees of freedom thinly; fitted-probability grouping can miss misfit that cancels along the predicted probability; covariate-clustering tests can miss smooth link departures.
- The chi-square reference is asymptotic and needs adequate group sizes.
DEF is built to fix the power cons without giving up size control: it keeps the intuitive fitted-probability grouping but directs the test at calibration-curve shapes, and the ensemble removes the basis choice by combining those directions — which is why it tops the table above while staying at the nominal size.
Setup: covariate x ~ Uniform(-3, 3), models fitted as glm(y ~ x); all tests
computed in one call with the package's own run.all.gof(). The dashed red line
marks the nominal 0.05 size.
Examples
Example 1: Basic Usage with Binary Data
library(ebrahim.gof)

# Simulate binary data
set.seed(42)
n <- 1000
x1 <- rnorm(n)
x2 <- rnorm(n)
linpred <- -0.5 + 0.8 * x1 + 0.6 * x2
prob <- plogis(linpred)
y <- rbinom(n, 1, prob)

# Fit logistic regression
model <- glm(y ~ x1 + x2, family = binomial())
predicted_probs <- fitted(model)

# Test goodness of fit (EF on ten groups, chi-square reference on G - 2 df)
result <- ef.gof(y, predicted_probs, G = 10)
print(result)
#>                 Test Test_Statistic p_value
#> 1 Ebrahim-Farrington         1.3731   0.096
Example 2: Compare Different Group Numbers
# Test with different numbers of groups
results <- data.frame(
  Groups = c(4, 10, 20),
  P_value = c(
    ef.gof(y, predicted_probs, G = 4)$p_value,
    ef.gof(y, predicted_probs, G = 10)$p_value,
    ef.gof(y, predicted_probs, G = 20)$p_value
  )
)
print(results)
Example 3: Comparison with Hosmer-Lemeshow Test
library(ResourceSelection)

# Ebrahim-Farrington test
ef_result <- ef.gof(y, predicted_probs, G = 10)

# Hosmer-Lemeshow test
hl_result <- hoslem.test(y, predicted_probs, g = 10)

# Compare results
comparison <- data.frame(
  Test = c("Ebrahim-Farrington", "Hosmer-Lemeshow"),
  P_value = c(ef_result$p_value, hl_result$p.value)
)
print(comparison)
Example 4: Power Analysis
# Function to simulate misspecified model
simulate_power <- function(n, beta_quad = 0.1, n_sims = 100) {
  rejections <- 0

  for (i in 1:n_sims) {
    x <- runif(n, -2, 2)
    # True model has quadratic term
    linpred_true <- 0 + x + beta_quad * x^2
    prob_true <- plogis(linpred_true)
    y <- rbinom(n, 1, prob_true)

    # Fit misspecified linear model
    model_mis <- glm(y ~ x, family = binomial())
    pred_probs <- fitted(model_mis)

    # Test goodness of fit
    test_result <- ef.gof(y, pred_probs, G = 10)

    if (test_result$p_value < 0.05) {
      rejections <- rejections + 1
    }
  }

  return(rejections / n_sims)
}

# Calculate power for different sample sizes
power_results <- data.frame(
  n = c(100, 200, 500, 1000),
  power = sapply(c(100, 200, 500, 1000), simulate_power)
)
print(power_results)
Example 5: Run the whole battery at once (run.all.gof)
library(ebrahim.gof)

# a model on the classic low-birth-weight data
fit <- glm(low ~ age + lwt + factor(race) + smoke,
           data = MASS::birthwt, family = binomial())

# every test in one tidy data frame (one row per test)
run.all.gof(fit)

# also run the opt-in slow tests (le Cessie, GAM-based, Stute-Zhu, eHL, BAGofT,
# Lai-Liu); set the bootstrap reps via control
run.all.gof(fit, include_slow = TRUE,
            control = list("Stute-Zhu" = list(B = 200)))

# or just a chosen subset
run.all.gof(fit, tests = c("EF", "DEF.poly3", "Tsiatis", "HL"))
Example 6: Directed test and the ensemble (def.gof, def.ensemble.gof)
set.seed(1)
n <- 800
x <- runif(n, -3, 3)
y <- rbinom(n, 1, 1 - exp(-exp(0.6 * x)))   # true link is complementary log-log
fit <- glm(y ~ x, family = binomial())       # fitted as logit (misspecified)

# the directed test with different shape bases
def.gof(fit, basis = "poly2")
def.gof(fit, basis = "stukel")

# the recommended default: combine the three bases with the Cauchy combination
# test (no basis to choose, valid size)
def.ensemble.gof(fit)
def.ensemble.gof(fit, add_ef = TRUE)   # also fold in the omnibus EF
Methodology
The Ebrahim-Farrington test is based on Farrington's (1996) theoretical framework but simplified for practical implementation with binary data. The test uses a modified Pearson chi-square statistic:
For binary data with automatic grouping, the test statistic is:
Z_EF = (T_EF - (G - 2)) / sqrt(2(G - 2))
Where:
T_EFis the modified Pearson chi-square statisticGis the number of groupsZ_EFfollows a standard normal distribution under H₀
As of version 2.0.0, ef.gof() by default refers T_EF directly to a
chi-square distribution with G - 2 degrees of freedom (method = "chisq"),
which is a more accurate small-sample reference; the standardized-normal form
Z_EF above is still available via method = "normal".
Advantages over Hosmer-Lemeshow Test
- Better Power: More sensitive to model misspecification
- Sparse Data Handling: Specifically designed for sparse data situations
- Computational Efficiency: Simplified calculations for binary data
- Theoretical Foundation: Based on rigorous asymptotic theory
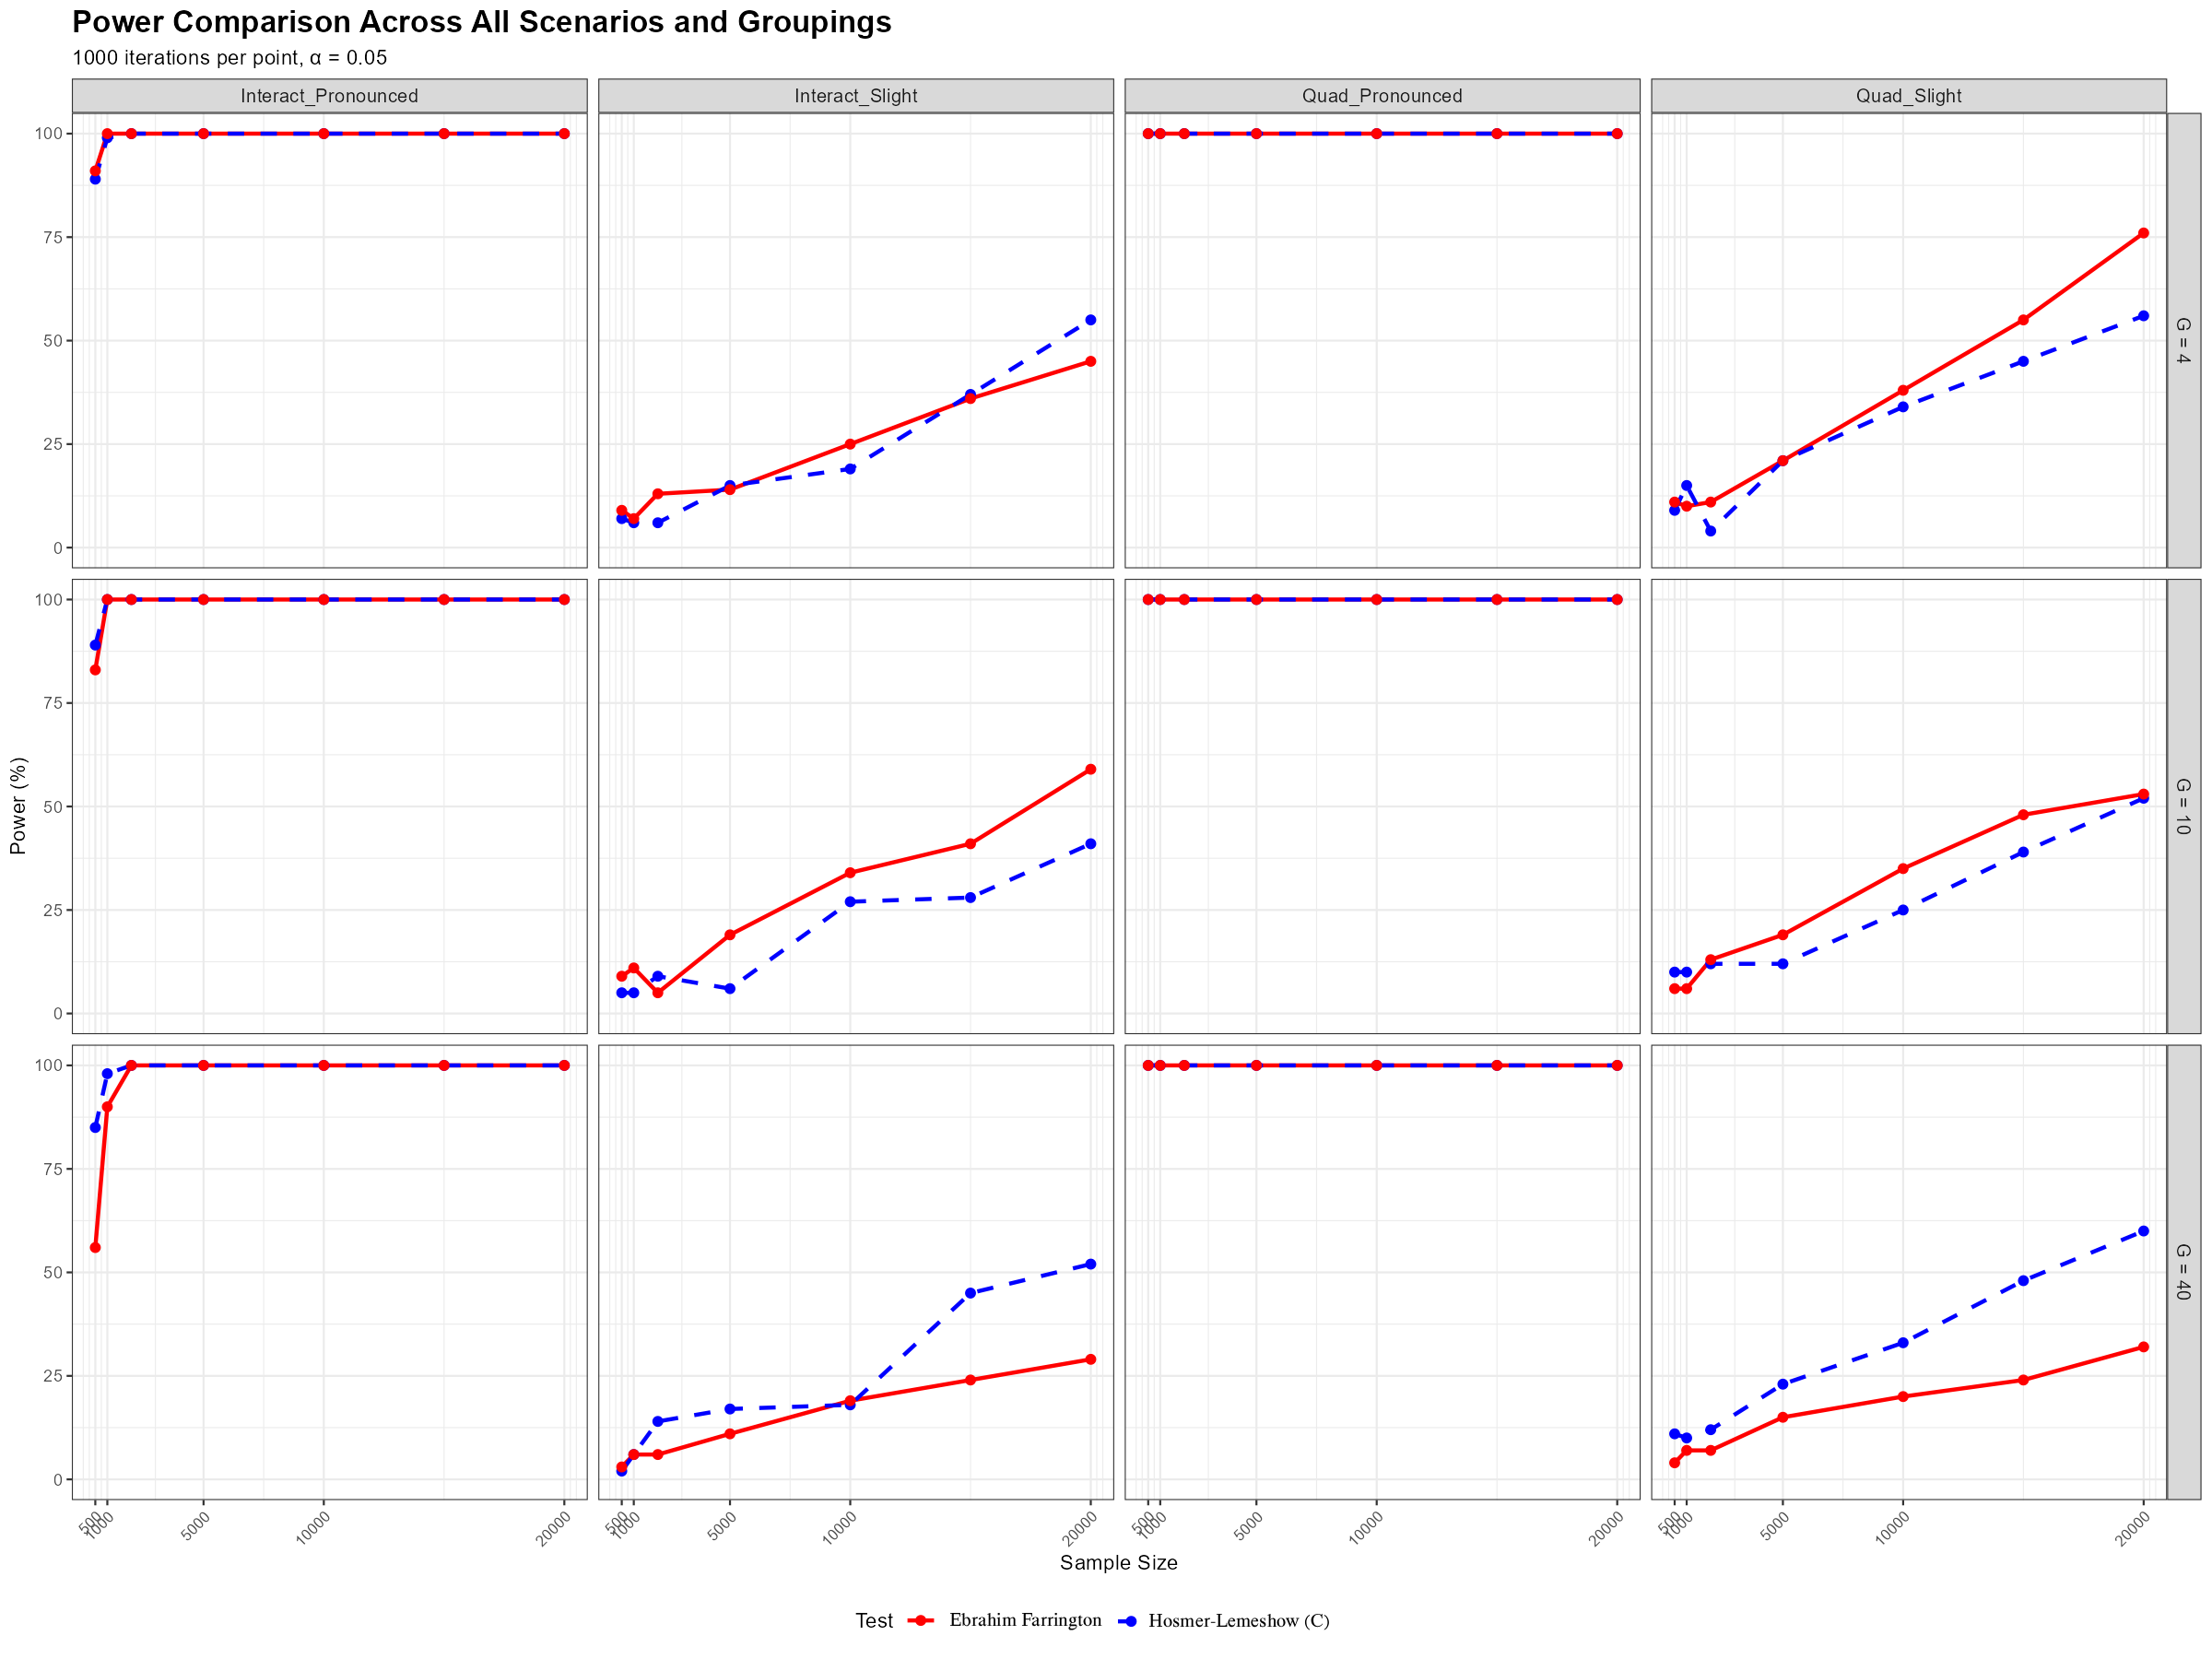
Superior Performance at G=10
Simulation results consistently demonstrate that the Ebrahim-Farrington test outperforms the Hosmer-Lemeshow test, even when the model misspecification is minimal—such as with a missing interaction or omitted quadratic term—when using G = 10 groups (Ebrahim, 2025).
Asymptotically Following the Standard Normal Distribution
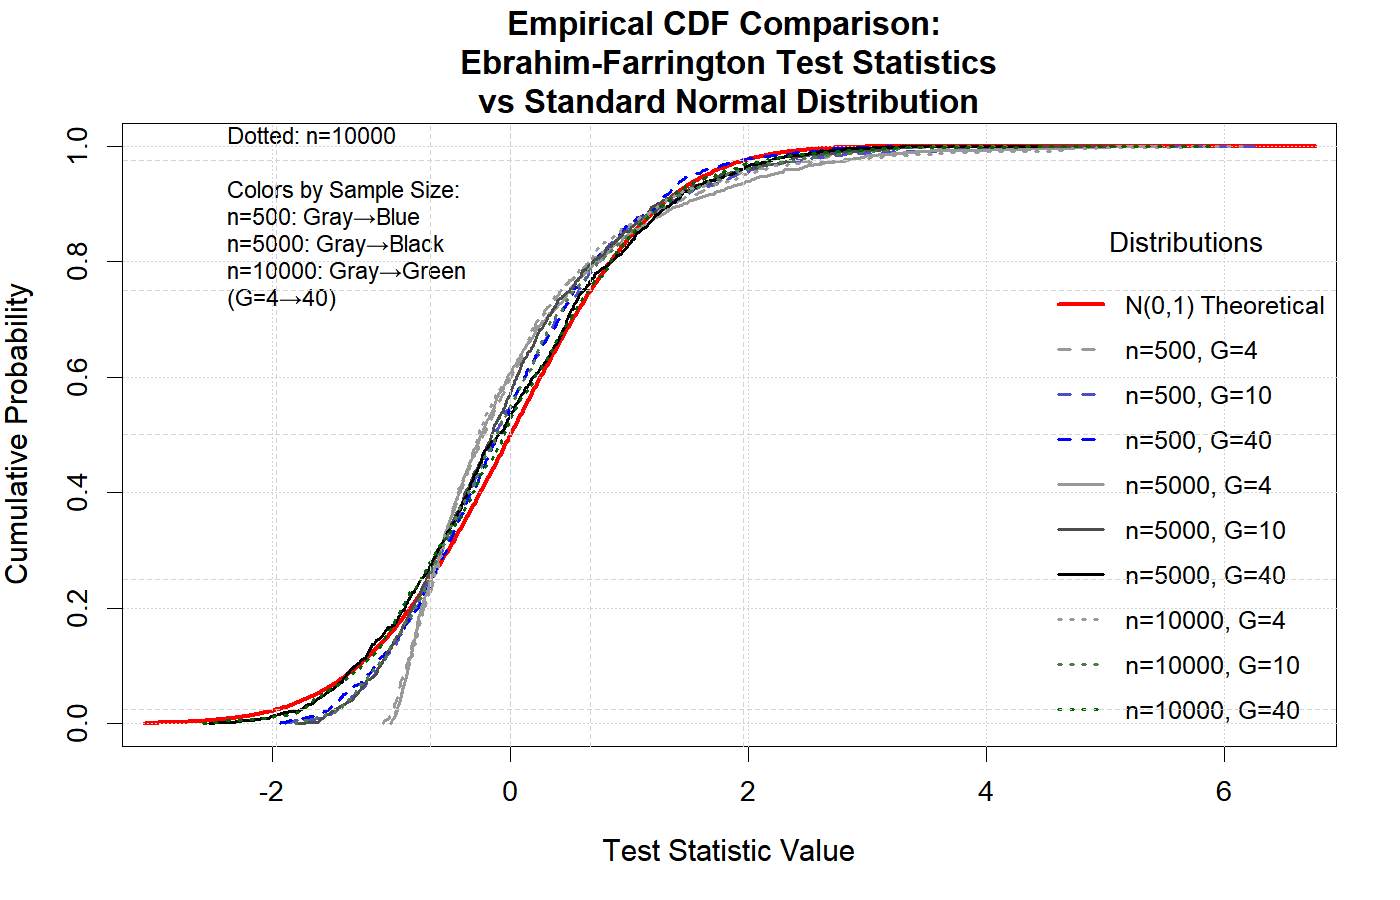
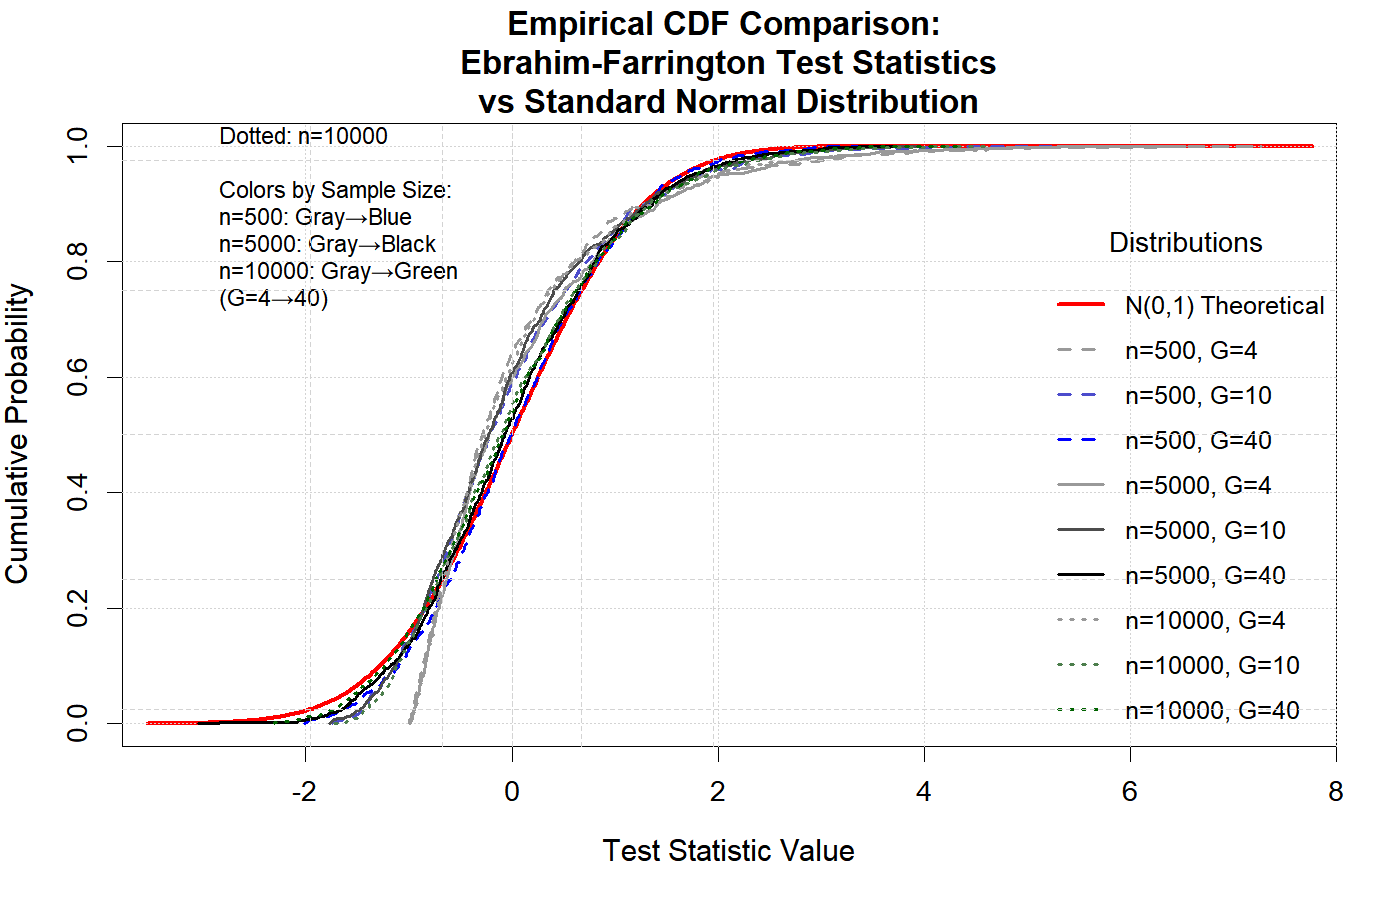
The following two figures illustrate that, under the null hypothesis, the Ebrahim-Farrington test statistic is asymptotically standard normal for both single-predictor and multiple-predictor logistic regression models. This property holds even in sparse data settings, confirming the theoretical foundation of the test and supporting its use for model assessment. (see (Ebrahim,2025))
- Figure 1: Empirical cumulative distribution function (CDF) of the Ebrahim-Farrington test statistic under the null for a single predictor, compared to the standard normal CDF.
- Figure 2: Empirical CDF for the test statistic under the null for a multiple independent predictors scenario, again compared to the standard normal.
These results demonstrate that the Ebrahim-Farrington test maintains the correct type I error rate and its statistic converges to the standard normal distribution as sample size increases, validating its asymptotic properties.
Performance: parallel and GPU
The battery is fast by default — the author's own tests (ef.gof(), edge.gof(),
def.ensemble.gof()) are closed-form and run in milliseconds. The cost comes from
a few classical resampling/quadratic-form tests when they are included.
Parallel bootstrap tests (built in)
Two of the slow tests — Stute–Zhu and Lai–Liu–HL — are bootstrap tests. Their resampling loops can be spread across CPU cores with a single flag:
# run just the bootstrap test on 4 workers
run.all.gof(fit, tests = "Stute-Zhu", parallel = TRUE, ncores = 4,
            control = list("Stute-Zhu" = list(B = 2000)))
- Uses a local PSOCK cluster from base R's
parallelpackage — works on all platforms, including Windows (not just fork-based Unix). ncores = NULL(default) usesdetectCores() - 1; values below 2 fall back to the sequential path.- Reproducible: with
parallel::clusterSetRNGStream, the sameset.seed()and the samencoresgive identical bootstrap p-values. - Default is
parallel = FALSE, so nothing changes unless you opt in. The gain is moderate (it targets the resampling loops only, and cluster setup has fixed overhead), so it pays off mainly at largeB.
Optional GPU path (replication scripts, not part of the package)
The most expensive aggregated tests — le Cessie–van Houwelingen and
McCullagh (dense O(n²)–O(n³) quadratic forms), plus the projection/RMEP bootstrap —
have GPU implementations (CuPy accessed via reticulate). These are not shipped in the
package: they need a CUDA + CuPy environment and would make the package non-portable, so
they live in the paper's replication scripts. Every GPU statistic is checked against the
CPU value to a relative tolerance of 1e-6 (identical, correct statistic — only faster):
| Test | n | CPU (s) | GPU (s) | Speed-up |
|---|---|---|---|---|
| le Cessie | 2000 | 14.81 | 0.20 | 74× |
| le Cessie | 5000 | 225.22 | 2.95 | 76× |
| McCullagh | 2000 | 14.54 | 0.03 | 485× |
| McCullagh | 5000 | 224.32 | 0.08 | 2804× |
| projection (RMEP) | 1000 | 28.75 | 1.22 | 24× |
These accelerate the classical rival tests so they stay usable for large-n
comparisons; the package's own directed tests are already fast on one CPU core. Full
benchmark: paper_JSS/replication/gpu_bench.R and gpu_bench.csv (see the JSS
companion paper, §5).
References
-
Farrington, C. P. (1996). On Assessing Goodness of Fit of Generalized Linear Models to Sparse Data. Journal of the Royal Statistical Society. Series B (Methodological), 58(2), 349-360.
-
Ebrahim, Khaled Ebrahim (2025). Goodness-of-Fits Tests and Calibration Machine Learning Algorithms for Logistic Regression Model with Sparse Data. Master's Thesis, Alexandria University.
-
Hosmer, D. W., & Lemeshow, S. (2000). Applied Logistic Regression, Second Edition. New York: Wiley.
Citation
If you use this package in your research, please cite it (run citation("ebrahim.gof")
in R for the up-to-date entries):
Ebrahim, E. K. (2026). ebrahim.gof: Goodness-of-Fit and Calibration Tests
for Logistic Regression. R package version 2.10.0.
https://github.com/ebrahimkhaled/ebrahim.gof
Related papers
The methods in this package are described in the following papers by the author (please cite the relevant one alongside the package):
- EDGE — the directed test (
edge.gof()/def.gof()): Ebrahim, E. K., Hussein, O. A. E.-A. & El-Kotory, A. (2026). A grouped calibration test for logistic regression that tolerates a few corrupted records. arXiv:2608.20511 - EF — the omnibus test (
ef.gof()): Ebrahim, E. K., Khattab, I. G. & El-Kotory, A. (2026). A modified Hosmer–Lemeshow goodness-of-fit test for asymmetric links: second-order power and robustness. arXiv:2607.15454 · Zenodo 10.5281/zenodo.21184547 - DeepGOF-1 — the pretrained test (
deepgof1(),deepgof1.external()): Ebrahim, E. K., Hussein, O. A. E.-A. & El-Kotory, A. (2026). Where does a logistic risk model fail? An audited neural goodness-of-fit test for model development and external validation. arXiv:2609.29575 - Shrinkage — penalized fits (
shrink.gof()): Ebrahim, E. K. (2026). Shrinkage invalidates the Hosmer–Lemeshow test: goodness of fit for penalized logistic regression, with an application to glaucoma diagnosis. arXiv:2609.06413 - Localization (
localize.gof(),localize.external()): Ebrahim, E. K., El-Kotory, A. & Hussein, O. A. E.-A. (2026). One goodness-of-fit test is not enough: error-controlled localization of misfit in logistic risk models. Preprint · Zenodo 10.5281/zenodo.23192535 - Benchmark — how the battery performs: Ebrahim, E. K. & El-Kotory, A. (2026). Benchmarking goodness-of-fit and calibration algorithms for logistic regression classifiers: a large-scale simulation study under sparse data. Journal of Intelligent Computing and Data Science 2(2), 97–128. 10.21608/jicds.2026.505341.1048 — an empirical comparison of the tests aggregated here (no single test wins across all alternatives).
- EDGES — the Cauchy-combination ensemble (
edges.gof()/def.ensemble.gof()): Ebrahim, E. K. & El-Kotory, A. (2026). A Cauchy-combination ensemble of directed goodness-of-fit tests. In preparation.
Contributing
Contributions are welcome! Please feel free to submit a Pull Request. For major changes, please open an issue first to discuss what you would like to change.
License
This project is licensed under the GPL-3 License
Author
Ebrahim Khaled Ebrahim
Alexandria University
Email: [email protected]
Acknowledgments
- Prof. Osama Abd ElAziz Hussien (Alexandria University) for supervision
- Dr. Ahmed El-Kotory (Alexandria University) for guidance and supervision
- The R community for continuous support and feedback
Reproducing published results
The EDGE paper's benchmarks correspond to version 2.4.0 (the CRAN release accompanying the papers). To install that exact version later, so the published examples reproduce even after newer releases:
remotes::install_version("ebrahim.gof", version = "2.4.0")