matchednull
Matched-Null Tests for Cluster-Count Claims
Builds matched nulls for cluster-count claims: synthetic twins of a
dataset that preserve every marginal distribution exactly and the
correlation matrix approximately, while containing no cluster structure by
construction. A reported number of clusters or "types" can then be tested
against what the data's own margins and covariance already produce, using
any clustering pipeline. A t-copula option is a sensitivity check that adds
tail dependence to the reference, so an apparent excess of clusters can be
rerun against a heavier-tailed reference; neither outcome of that rerun
establishes that types exist. Implements the matched-null procedure of Meng (2026) "Types
Without Taxa"
matchednull 


Clustering methods will always give you clusters, even when the data are one smooth cloud. That makes it hard to know whether the reported clusters reflect real structure or are simply artifacts of the method.
matchednull helps you find out. It creates a null twin of your dataset with exactly the same marginal distributions and approximately the same correlation structure, but no cluster structure by construction. You then run your own clustering pipeline on both the observed data and the null twins. If the observed data yield more clusters than the null twins, they carry structure that a reference with their margins and correlations does not, which is where a types claim can start rather than where it ends. If they don't, you'll know before a reviewer asks.
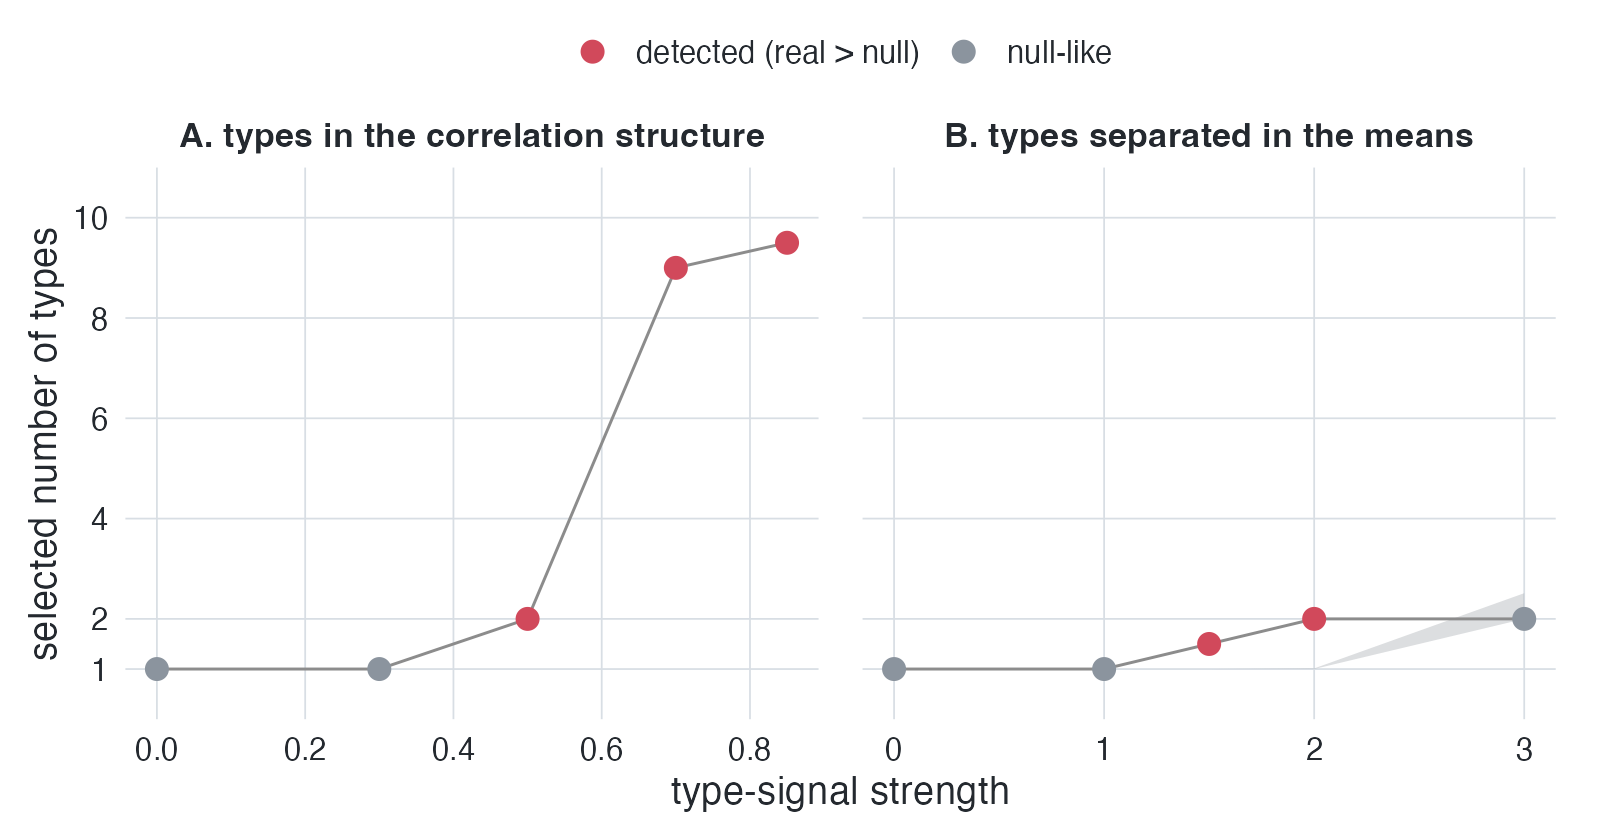
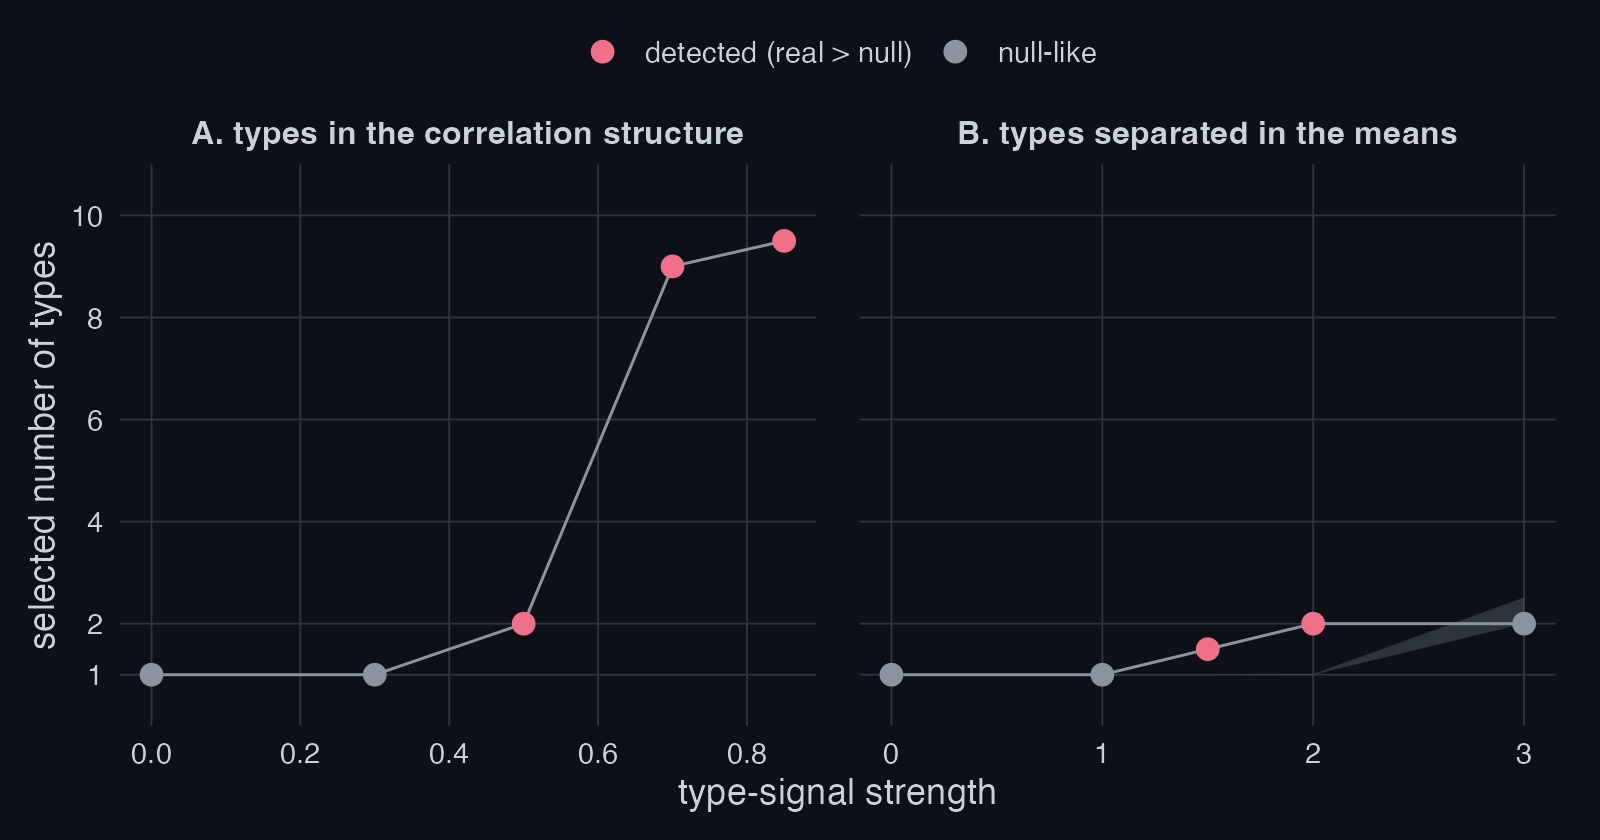
Positive controls. Signal strength is the within-component correlation in panel A and the separation between means, in standard deviations, in panel B. The grey shaded band is the matched null's 95% interval: a point is red (detected) when the real number of clusters exceeds the band, grey (the legend's null-like label, meaning within the reference interval) when it falls inside. The test finds real types whether they live only in the correlation structure (A) or in well-separated means (B).
One thing in that figure is worth a second look: in panel B the test stops firing at the largest separation, which is the opposite of what a power curve should do. How it works follows the construction out to that point, explains what the test is declining to answer there, and shows the calibration behind the rest of the figure.
copula_null() generates the null twins, preserving every marginal
distribution exactly (each twin column is a permutation of the observed
values) and reproducing the correlation matrix approximately: the observed
correlation matrix is used as the latent correlation of the copula, and
non-normal margins move the output Pearson correlations, so they come out
close but not exact. matched_null_test() applies any user-supplied
clustering pipeline to the observed data and to R null twins, then reports
whether the observed result stands out from the twins. Its p_exceed is a
plug-in Monte Carlo exceedance quantity under a reference fitted to the same
data, not an exact finite-sample p-value.
Installation
install.packages("matchednull")

# development version
remotes::install_github("haomeng797-ship-it/matchednull")
Quick example
library(matchednull)
library(mclust)

pick_k <- function(d) Mclust(d, G = 1:5, verbose = FALSE)$G

set.seed(1)
x <- matrix(rnorm(500 * 4), 500, 4)   # typeless data
set.seed(2)
matched_null_test(x, pick_k, R = 50)
#> Matched-null test (50 Gaussian null twins)
#>   real statistic:               1
#>   null interval:                [1, 1]
#>   MC exceedance (null >= real): 1
#>   outcome:                      no detected excess (within the reference interval)
See vignette("matchednull") for the full walk-through, including a case
where genuine types hide in the dependence structure and the test fires.
In our calibration runs on skewed but clusterless data (100 datasets each at n = 500 and n = 2,000, with the search range set wide enough that the count being tested never reached its upper limit), BIC and ICL chose more than one cluster in every dataset. The matched-null test flagged 4 of 100 at each sample size, close to the 2.5% expected by chance under its rule.
Reference
The method, its positive controls, and its false-positive calibration are described in the accompanying paper, A Matched-Null Test of Whether the Clusters a Pipeline Reports Are Real, With an Application to Personality Types (Meng, 2026, under review). Its personality application was preregistered as Types Without Taxa (https://osf.io/2ekcg).